Losses and Errors
In general we distinguish between losses that are used during training of a neural network and errors that arise in the context of reduced order modeling.
Different Neural Network Losses
GeometricMachineLearning has a number of loss functions implemented that can be called standard losses. Those are the FeedForwardLoss (defined in AbstractNeuralNetworks), the TransformerLoss, the AutoEncoderLoss and the ReducedLoss. How to implement custom losses is shown in a tutorial.
A Note on Physics-Informed Neural Networks
A popular trend in recent years has been considering known physical properties of the differential equation, or the entire differential equation, through the loss function [52]. This is one way of considering physical properties, and GeometricMachineLearning allows for a flexible implementation of custom losses, but this is nonetheless discouraged. In general a neural networks consists of three ingredients:
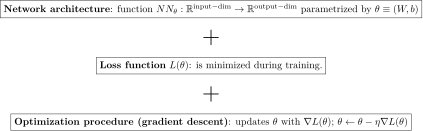

Instead of considering certain properties through the loss function, we instead do so by enforcing them strongly through the network architecture and the optimizer; the latter pertains to manifold optimization. The advantages of this approach are the strong enforcement of properties that we know our network should have and much easier training because we do not have to tune hyperparameters.
Projection and Reduction Errors of Reduced Models
Two errors that are of very big importance in reduced order modeling are the projection and the reduction error. During training one typically aims at minimizing the projection error, but for the actual application of the model the reduction error is often more important.
Projection Error
The projection error computes how well a reduced basis, represented by the reduction $\mathcal{P}$ and the reconstruction $\mathcal{R}$, can represent the data with which it is build. In mathematical terms:
\[ e_\mathrm{proj}(\mu) := \frac{|| \mathcal{R}\circ\mathcal{P}(M) - M ||}{|| M ||},\]
where $||\cdot||$ is the Frobenius norm (one could also optimize for different norms). The corresponding function in GeometricMachineLearning is projection_error. The projection error is equivalent to AutoEncoderLoss and is used for training under that name.
Reduction Error
The reduction error measures how far the reduced system diverges from the full-order system during integration (online stage). In mathematical terms (and for a single initial condition):
\[e_\mathrm{red}(\mu) := \sqrt{ \frac{\sum_{t=0}^K|| \mathbf{x}^{(t)}(\mu) - \mathcal{R}(\mathbf{x}^{(t)}_r(\mu)) ||^2}{\sum_{t=0}^K|| \mathbf{x}^{(t)}(\mu) ||^2} },\]
where $\mathbf{x}^{(t)}$ is the solution of the FOM at point $t$ and $\mathbf{x}^{(t)}_r$ is the solution of the ROM (in the reduced basis) at point $t$. The reduction error, as opposed to the projection error, not only measures how well the solution manifold is represented by the reduced basis, but also measures how well the FOM dynamics are approximated by the ROM dynamics (via the induced vector field on the reduced basis). The corresponding function in GeometricMachineLearning is reduction_error. The reduction error is, in contract to the projection error, typically not used during training (even though some authors are using a similar error to do so [42]).
Library Functions
GeometricMachineLearning.TransformerLoss — Type
TransformerLoss(seq_length, prediction_window)Make an instance of the transformer loss.
This should be used together with a neural network of type TransformerIntegrator.
Example
TransformerLoss applies a neural network to an input and compares it to the output via an $L_2$ norm:
using GeometricMachineLearning
using LinearAlgebra: norm
import Random

const d = 2
const seq_length = 3
const prediction_window = 2

Random.seed!(123)
arch = StandardTransformerIntegrator(d)
nn = NeuralNetwork(arch)

input_mat =  [1. 2. 3.; 4. 5. 6.]
output_mat = [1. 2.; 3. 4.]
loss = TransformerLoss(seq_length, prediction_window)

# start of prediction
const sop = seq_length - prediction_window + 1
loss(nn, input_mat, output_mat) ≈ norm(output_mat - nn(input_mat)[:, sop:end]) / norm(output_mat)

# output

true
So TransformerLoss simply does:
\[ \mathtt{loss}(\mathcal{NN}, \mathtt{input}, \mathtt{output}) = || \mathcal{NN}(\mathtt{input})[(\mathtt{sl} - \mathtt{pw} + 1):\mathtt{end}] - \mathtt{output} || / || \mathtt{output} ||,\]
where $||\cdot||$ is the $L_2$ norm.
Parameters
The prediction_window specifies how many time steps are predicted into the future. It defaults to the value specified for seq_length.
GeometricMachineLearning.AutoEncoderLoss — Type
AutoEncoderLoss()Make an instance of AutoEncoderLoss.
This loss should always be used together with a neural network of type AutoEncoder (and it is also the default for training such a network).
Example
AutoEncoderLoss applies a neural network to an input and compares it to the input via an $L_2$ norm:
using GeometricMachineLearning
using LinearAlgebra: norm
import Random
Random.seed!(123)

const N = 4
const n = 1
arch = SymplecticAutoencoder(2*N, 2*n)
nn = NeuralNetwork(arch)

input_vec =  [1., 2., 3., 4., 5., 6., 7., 8.]
loss = AutoEncoderLoss()

loss(nn, input_vec) ≈ norm(input_vec - nn(input_vec)) / norm(input_vec)

# output

true
So AutoEncoderLoss simply does:
\[ \mathtt{loss}(\mathcal{NN}, \mathtt{input}) = || \mathcal{NN}(\mathtt{input}) - \mathtt{input} || / || \mathtt{input} ||,\]
where $||\cdot||$ is the $L_2$ norm.
Parameters
This loss does not have any parameters. The four-argument method reconstructs its input and ignores the target it is given, so an autoencoder is trained on the input alone.
GeometricMachineLearning.ReducedLoss — Type
ReducedLoss(encoder, decoder)Make an instance of ReducedLoss based on an Encoder and a Decoder.
This loss should be used together with a NeuralNetworkIntegrator or TransformerIntegrator.
Example
ReducedLoss applies the encoder, integrator and decoder neural networks in this order to an input and compares it to the output via an $L_2$ norm:
using GeometricMachineLearning
using LinearAlgebra: norm
import Random
Random.seed!(123)

const N = 4
const n = 1

Ψᵉ = NeuralNetwork(Chain(Dense(N, n), Dense(n, n))) |> encoder
Ψᵈ = NeuralNetwork(Chain(Dense(n, n), Dense(n, N))) |> decoder
transformer = NeuralNetwork(StandardTransformerIntegrator(n))

input_mat =  [1.  2.;  3.  4.;  5.  6.;  7.  8.]
output_mat = [9. 10.; 11. 12.; 13. 14.; 15. 16.]
loss = ReducedLoss(Ψᵉ, Ψᵈ)

output_prediction = Ψᵈ(transformer(Ψᵉ(input_mat)))
loss(transformer, input_mat, output_mat) ≈ norm(output_mat - output_prediction) / norm(output_mat)

# output

true
So the loss computes:
\[\mathrm{loss}_{\mathcal{E}, \mathcal{D}}(\mathcal{NN}, \mathrm{input}, \mathrm{output}) = ||\mathcal{D}(\mathcal{NN}(\mathcal{E}(\mathrm{input}))) - \mathrm{output}||,\]
where $\mathcal{E}$ is the Encoder, $\mathcal{D}$ is the Decoder. $\mathcal{NN}$ is the neural network we compute the loss of.
GeometricMachineLearning.CharbonnierRelativeLoss — Type
CharbonnierRelativeLoss(; ε = 1e-3, λ_lat = 1e-2)Smooth Charbonnier relative reconstruction and latent consistency loss:
\[\mathcal{L}_{\mathrm{Charb}}(\hat{x}, x) = \frac{\sqrt{\|\hat{x} - x\|_F^2 + \varepsilon^2} - \varepsilon}{\sqrt{\|x\|_F^2 + \varepsilon^2}} + \lambda_{\mathrm{lat}}\,\frac{\|\mathrm{encode}(nn, m, \hat{x}) - \mathrm{encode}(nn, m, x)\|_F^2}{\|x\|_F^2 + \varepsilon^2}.\]
Called as loss(nn, m, x̂, x), it takes an external reconstruction $\hat{x}$. Called as loss(nn, m, x) (or loss(nn, x) for the first modality), it uses $\hat{x} = \mathrm{decode}(nn, m, \mathrm{encode}(nn, m, x))$.
Both forms compare $\hat{x}$ with $x$ in the form that decode returns: a pre-split pair (q = F⁺, p = F⁻) of a BilinearStiefelLayer modality, passed as $x$ or as $\hat{x}$, is recombined into the full field. The two halves of such a pair have one element type; halves of different element types raise an ArgumentError.
Here $\varepsilon > 0$ (default 1e-3) regularizes the Frobenius norm at $\hat{x} = x$ and $x = 0$, and $\lambda_{\mathrm{lat}} \ge 0$ (default 1e-2) weights the latent re-encoding consistency penalty.
When $x = 0$ and $\hat{x} = 0$, the loss returns exact zero(T) (not NaN), and its gradient at $\hat{x} = x$ is finite and zero (0 / ε = 0).
GeometricMachineLearning.IsometricRolloutLoss — Type
IsometricRolloutLoss(integrator; α_lat = 1.0, α_rec = 1.0, α_H = 0.0, H = nothing)Multi-step latent rollout, decoded trajectory reconstruction, and latent Hamiltonian conservation loss:
\[\mathcal{L}_{\mathrm{roll}} = \frac{1}{K - 1}\sum_{k=2}^{K} \left( \alpha_{\mathrm{lat}}\,\|\hat{z}_k - z_k\|_F^2 + \alpha_{\mathrm{rec}}\,\|\mathrm{decode}(nn, m, \hat{z}_k) - x_k\|_F^2 + \alpha_H\,\bigl|H(\hat{z}_k) - H(\hat{z}_1)\bigr|^2 \right),\]
where $z_k = \mathrm{encode}(nn, m, x_k)$, $\hat{z}_1 = z_1$, $\hat{z}_{k+1} = \mathrm{integrator}(\hat{z}_k)$ for $k = 1, \dots, K - 1$, and H is a callable latent Hamiltonian. H(ẑ) takes the latent state as encode and integrator give it, a vector of length $2n$ or a matrix of size $(2n, B)$ for a batched snapshot, and returns one scalar, one value for a whole batch. The decoded state is compared with $x_k$ in the form that decode returns: a pre-split pair (q = F⁺, p = F⁻) of a BilinearStiefelLayer modality is recombined into the full field. The weights default to α_lat = 1.0, α_rec = 1.0, and α_H = 0.0, so IsometricRolloutLoss(integrator) has no energy term.
H has no default: the loss requires a latent Hamiltonian H when α_H > 0, and the constructor raises an ArgumentError without one. A fixed latent energy such as $\frac{1}{2}\|\hat{z}\|_2^2$ is not the energy of the system. With α_H = 0, the loss has no energy term and takes no H: a given H would have no effect, so the constructor raises an ArgumentError. The data, the output of integrator and, with α_H > 0, the value of H have the element type of the network's parameters; another element type raises an ArgumentError.
GeometricMachineLearning.CrossModalLoss — Type
CrossModalLoss(mod_a::Symbol, mod_b::Symbol; β_align = 1.0, β_cross = 1.0)Cross-modal paired latent alignment and cross-reconstruction loss between modalities mod_a and mod_b:
\[\mathcal{L}_{\mathrm{cross}}(x_a, x_b) = \beta_{\mathrm{align}}\,\|z_a - z_b\|_F^2 + \beta_{\mathrm{cross}}\,\|\mathrm{decode}(nn, b, z_a) - x_b\|_F^2,\]
where $z_a = \mathrm{encode}(nn, a, x_a)$ and $z_b = \mathrm{encode}(nn, b, x_b)$. The pair $(x_a, x_b)$ is the same physical state in two modalities: the alignment term asks that both encode to one latent state, and the cross-reconstruction term asks that the latent state of $x_a$ decodes to $x_b$. The loss is not symmetric in $a$ and $b$: the cross-reconstruction term decodes only into modality mod_b, so CrossModalLoss(mod_b, mod_a) is another loss. decode(nn, b, z_a) is compared with $x_b$ in the form that decode returns: a pre-split pair (q = F⁺, p = F⁻) of a BilinearStiefelLayer modality is recombined into the full field. A batch is the sum of its samples' losses; x_a and x_b with different numbers of samples raise a DimensionMismatch.
The weights are non-negative and default to β_align = 1.0 and β_cross = 1.0; a negative or NaN weight raises an ArgumentError. x_a and x_b have the element type of the network's parameters; another element type raises an ArgumentError.
GeometricMachineLearning.ParametricLoss — Type
ParametricLoss()Make an instance of the loss of a network whose forward pass takes the parameters $\mu$ of the system beside its input.
ParametricLoss()(model, ps, input, output, μ) applies the network with apply_parametric and compares the result with output in the relative $L_2$ norm:
\[\mathrm{loss}(\mathcal{NN}, \mathrm{input}, \mathrm{output}, \mu) = ||\mathcal{NN}(\mathrm{input}, \mu) - \mathrm{output}|| / ||\mathrm{output}||.\]
This is FeedForwardLoss with the system parameters passed to the network. μ is one OptionalParameters for one sample, or a vector of them, one per sample of a batch, as a ParametricDataLoader draws it. train! on a ParametricDataLoader trains on this loss when no loss is given.
GeometricMachineLearning.apply_parametric — Function
apply_parametric(model, x, μ, ps)Apply the Chain model with the network parameters ps to the input x and the parameters μ of the system.
x is one sample — a vector, or a (q, p) named tuple of vectors — with one μ, an OptionalParameters. Or x is a batch of k samples — a 2d × 1 × k tensor, or a (q, p) named tuple of d × 1 × k tensors — with a vector of k values of μ, one per sample, as a ParametricDataLoader draws them. A batch holds at least one sample. The output has the shape of the input.
The Chain receives the pair (x, μ), so its first layer takes one sample and its μ, and a layer that returns such a pair passes μ on to the next. A batch is applied sample by sample.
Examples
using GeometricMachineLearning
using GeometricMachineLearning: apply_parametric
import AbstractNeuralNetworks: AbstractExplicitLayer

# a layer that adds the system parameter `a` to its input
struct AddParameter <: AbstractExplicitLayer{2, 2} end
(::AddParameter)((x, μ)::Tuple, ps) = x .+ μ.a

model = Chain(AddParameter())
ps = NetworkParameters((L1 = NamedTuple(),))
x = reshape([1.0, 2.0, 3.0, 4.0], 2, 1, 2)
apply_parametric(model, x, [(a = 10.0,), (a = 20.0,)], ps)

# output

2×1×2 Array{Float64, 3}:
[:, :, 1] =
 11.0
 12.0

[:, :, 2] =
 23.0
24.0GeometricMachineLearning.projection_error — Function
projection_error(rs)Compute the projection error for a HRedSys.
Arguments
If the full system has already been integrated, then the projection error can be computed quicker:
projection_error(rs, sol_full)This saves the cost of again integrating the systems.
GeometricMachineLearning.reduction_error — Function
reduction_error(rs)Compute the reduction error for a HRedSys.
Arguments
If the full system and the reduced system have already been integrated, then the reduction error can be computed quicker:
reduction_error(rs, sol_full, sol_reduced)This saves the cost of again integrating the respective systems.
References
- [42]
- K. Lee and K. T. Carlberg. Model reduction of dynamical systems on nonlinear manifolds using deep convolutional autoencoders. Journal of Computational Physics 404, 108973 (2020).
- [52]
- M. Raissi, P. Perdikaris and G. E. Karniadakis. Physics-informed neural networks: A deep learning framework for solving forward and inverse problems involving nonlinear partial differential equations. Journal of Computational physics 378, 686–707 (2019).