The Symplectic Autoencoder
Symplectic autoencoders offer a structure-preserving way of mapping a high-dimensional system to a low-dimensional system. Concretely this means that if we obtain a reduced system by means of a symplectic autoencoder, this system will again be symplectic; we can thus model a symplectic FOM with a symplectic ROM.
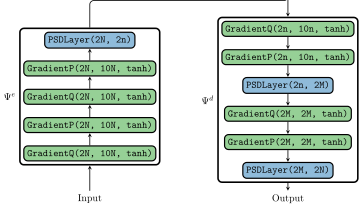
The architecture is represented by the figure below[1]:
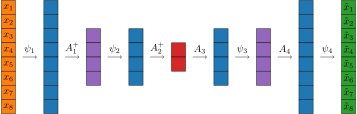
It is a composition of SympNet gradient layers and PSD-like matrices, so a matrix $A_i$ (respectively $A_i^+$) is of the form
\[ A_i^{(+)} = \begin{bmatrix} \Phi_i & \mathbb{O} \\ \mathbb{O} & \Phi_i \end{bmatrix} \text{ where }\begin{cases} \Phi_i\in{}St(d_{i},d_{i+1})\subset\mathbb{R}^{d_{i+1}\times{}d_i} & \text{if $d_{i+1} > d_i$} \\ \Phi_i\in{}St(d_{i+1},d_{i})\subset\mathbb{R}^{d{i}\times{}d_{i+1}} & \text{if $d_i > d_{i+1}$}, \end{cases}\]
where $A_i^{(+)} = A_i$ if $d_{i+1} > d_i$ and $A_i^{(+)} = A_i^+$ if $d_{i+1} < d_i.$ Also note that for cotangent lift-like matrices we have
\[\begin{aligned} A_i^+ = \mathbb{J}_{2N} A_i^T \mathbb{J}_{2n}^T & = \begin{bmatrix} \mathbb{O}_{n\times{}n} & \mathbb{I}_n \\ -\mathbb{I}_n & \mathbb{O}_{n\times{}n} \end{bmatrix} \begin{bmatrix} \Phi_i^T & \mathbb{O}_{n\times{}N} \\ \mathbb{O}_{n\times{}N} & \Phi_i^T \end{bmatrix} \begin{bmatrix} \mathbb{O}_{N\times{}N} & - \mathbb{I}_N \\ \mathbb{I}_N & \mathbb{O}_{N\times{}N} \end{bmatrix} \\ & = \begin{bmatrix} \Phi_i^T & \mathbb{O}_{n\times{}N} \\ \mathbb{O}_{n\times{}N} & \Phi_i^T \end{bmatrix} = A_i^T, \end{aligned}\]
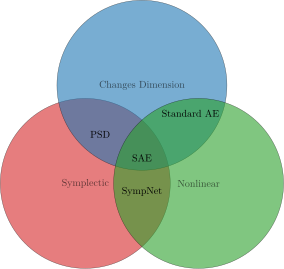
so the symplectic inverse is equivalent to a matrix transpose in this case. In the symplectic autoencoder we use SympNets as a form of symplectic preprocessing before the linear symplectic reduction (i.e. the PSD layer) is employed. The resulting neural network has some of its weights on manifolds, which is why we cannot use standard neural network optimizers, but have to resort to manifold optimizers. Note that manifold optimization is not necessary for the weights corresponding to the SympNet layers, these are still updated with standard neural network optimizers during training. Also note that SympNets are nonlinear and preserve symplecticity, but they cannot change the dimension of a system while PSD layers can change the dimension of a system and preserve symplecticity, but are strictly linear. Symplectic autoencoders have all three properties: they preserve symplecticity, can change dimension and are nonlinear mappings. We can visualize this in a Venn diagram:
We now show the proof that shows $\nabla_{\mathcal{R}(z)}\psi = (\nabla_{z}\mathcal{R})^+$ which was used when showing the equivalence between Hamiltonian systems on the full and the reduced space:
Proof
The symplectic autoencoder is a composition of $G$-SympNet layers and PSD-like matrices:
\[\Psi^d = A_n\circ\psi_n\circ\cdots\circ{}A_1\circ\psi_1.\]
It's local inverse is
\[(\Psi^d)^{-1} = \psi_1^{-1}\circ{}A_1^+\circ\ldots\circ\psi_n^{-1}\circ{}A_n^+.\]
The jacobian of $\Psi^d$ is:
\[\nabla_z\Psi^d = A_n\nabla_{A_{n-1}\cdots{}A_1\psi_1(z)}\psi_n\cdots{}A_1\nabla_z\psi_1,\]
and thus
\[(\nabla_z\Psi^d)^+ = (\nabla\psi)^+A_1^+\cdots(\nabla\psi_n)^+A_n^+,\]
where we dropped the argument in the derivative of the nonlinear parts. We further have
\[A^+ = A^T\]
for PSD-like matrices and
\[(\nabla_z\psi)^+ = \begin{pmatrix} \mathbb{O} & \mathbb{I} \\ -\mathbb{I} & \mathbb{O} \end{pmatrix} \begin{pmatrix} \mathbb{I} & \nabla_pf \\ \mathbb{O} & \mathbb{I} \end{pmatrix}^T \begin{pmatrix} \mathbb{O} & -\mathbb{I} \\ \mathbb{I} & \mathbb{O} \end{pmatrix} = \begin{pmatrix} \mathbb{I} & -\nabla_pf \\ \mathbb{O} & \mathbb{I} \end{pmatrix},\]
for the $G$-SympNet layers, where we assumed that $\psi$ only changes the $q$ component. Because these matrices are square, the inverse $(\nabla\psi)^+ = (\nabla\psi)^{-1}$ is unique.
The SympNet layers in the symplectic autoencoder operate in intermediate dimensions (as well as the input and output dimensions). In the following we explain how GeometricMachineLearning computes those intermediate dimensions.
Intermediate Dimensions
For a high-fidelity system of dimension $2N$ and a reduced system of dimension $2n$, the intermediate dimensions in the symplectic encoder and the decoder are computed according to:
iterations = Vector{Int}(n : (N - n) ÷ (n_blocks - 1) : N)
iterations[end] = full_dim2
iterations * 2
So for e.g. $2N = 100,$ $2n = 10$ and $\mathtt{n\_blocks} = 3$ we get
\[\mathrm{iterations} = 5\mathtt{:}(45 \div 2)\mathtt{:}50 = 5\mathtt{:}22\mathtt{:}50 = (5, 27, 49).\]
We still have to perform the two other modifications in the algorithm above:
iterations[end] = full_dim2$\ldots$ assignfull_dim2to the last entry,iterations * 2$\ldots$ multiply all the intermediate dimensions by two.
The resulting dimensions are:
\[(10, 54, 100).\]
The second step (the multiplication by two) is needed to arrive at intermediate dimensions that are even. This is necessary to preserve the canonical symplectic structure of the system.
Example
A visualization of an instance of SymplecticAutoencoder is shown below:
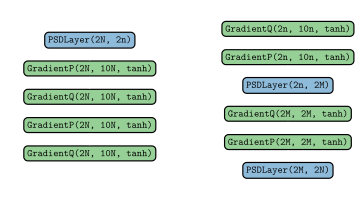
In this figure we have the following configuration: n_encoder_blocks is two, n_encoder_layers is four, n_decoder_blocks is three and n_decoder_layers is two. For a full dimension of 100 and a reduced dimension of ten we can build such an instance of a symplectic autoencoder by calling:
using GeometricMachineLearning

const full_dim = 100
const reduced_dim = 10

model = SymplecticAutoencoder(full_dim, reduced_dim;
                                                    n_encoder_blocks = 2,
                                                    n_encoder_layers = 4,
                                                    n_decoder_blocks = 3,
                                                    n_decoder_layers = 2)

for layer in Chain(model)
    println(stdout, layer)
end
GradientLayerQ{100, 100, typeof(tanh)}(500, tanh)
GradientLayerP{100, 100, typeof(tanh)}(500, tanh)
GradientLayerQ{100, 100, typeof(tanh)}(500, tanh)
GradientLayerP{100, 100, typeof(tanh)}(500, tanh)
PSDLayer{100, 10}()
GradientLayerQ{10, 10, typeof(tanh)}(50, tanh)
GradientLayerP{10, 10, typeof(tanh)}(50, tanh)
PSDLayer{10, 54}()
GradientLayerQ{54, 54, typeof(tanh)}(270, tanh)
GradientLayerP{54, 54, typeof(tanh)}(270, tanh)
PSDLayer{54, 100}()We also see that the intermediate dimension in the decoder is 54 for the specified dimensions and n_decoder_blocks = 3 as was outlined before.
Library Functions
GeometricMachineLearning.SymplecticAutoencoder — Type
SymplecticAutoencoder(full_dim, reduced_dim)Make an instance of SymplecticAutoencoder for dimensions full_dim and reduced_dim.
The architecture
The symplectic autoencoder architecture was introduced in [3]. Like any other autoencoder it consists of an encoder $\Psi^e:\mathbb{R}^{2N}\to\mathbb{R}^{2n}$ and a decoder $\Psi^d:\mathbb{R}^{2n}\to\mathbb{R}^{2N}$ with $n\ll{}N$. These satisfy the following properties:
\[\begin{aligned} \nabla_z\Psi^e\mathbb{J}_{2N}(\nabla_z\Psi^e\mathbb{J}_{2N})^T = \mathbb{J}_{2n} & \quad\text{and} \\ (\nabla_\xi\Psi^d)^T\mathbb{J}_{2N}\nabla_\xi\Psi^d = \mathbb{J}_{2n}. & \end{aligned}\]
Because the decoder has this particular property, the reduced system can be described by the Hamiltonian $H\circ\Psi^d$:
\[\mathbb{J}_{2n}\nabla_\xi(H\circ\Psi^d) = \mathbb{J}_{2n}(\nabla_\xi\Psi^d)^T\nabla_{\Psi^d(\xi)}H = \mathbb{J}_{2n}(\nabla_\xi\Psi^d)^T\mathbb{J}_{2N}^T\mathbb{J}_{2N}\nabla_{\Psi^d(\xi)}H = (\nabla_\xi\Psi^d)^+X_H(\Psi^d(\xi)),\]
where $(\nabla_\xi\Psi^d)^+$ is the symplectic inverse of $\nabla_\xi\Psi^d$ (for more details see the docs on the AutoEncoder type).
Arguments
Besides the required arguments full_dim and reduced_dim you can provide the following keyword arguments:
n_encoder_layers::Integer = 4: The number of layers in one encoder block.n_encoder_blocks::Integer = 2: The number of encoder blocks.n_decoder_layers::Integer = 1: The number of layers in one decoder block.n_decoder_blocks::Integer = 3: The number of decoder blocks.n_decoder_output_layers::Integer = 0: The number of additional nonlinear SympNet gradient layers appended after the final (linear) PSD layer of the decoder. These layers operate atfull_dimand provide extra expressivity to the decoder. When set to0(the default) the decoder ends with the standard linear PSD layer.sympnet_upscale::Integer = 5: The upscaling dimension of the GSympNet. SeeGradientLayerQandGradientLayerP.activation = tanh: The activation in the gradient layers.encoder_init_q::Bool = true: Specifies if the first layer in each encoder block should be of $q$ type.decoder_init_q::Bool = true: Specifies if the first layer in each decoder block should be of $q$ type.
GeometricMachineLearning.WeightTiedSymplecticAutoencoder — Type
WeightTiedSymplecticAutoencoder(full_dim, reduced_dim; kwargs...)Make an instance of a weight-tied symplectic autoencoder for ambient dimension full_dim ($2N$) and latent dimension reduced_dim ($2n$).
Unlike SymplecticAutoencoder, which maintains independent parameter trees for the encoder and decoder, WeightTiedSymplecticAutoencoder stores a single parameter tree ps for the stage blocks from reduced_dim up to full_dim:
decoder(nn)(ξ)applies the stage blocks in forward order (fromreduced_dimtofull_dim), embedding $\mathbb{R}^{2n} \to \mathbb{R}^{2N}$ via alternatingGradientLayerQ/GradientLayerPlayers and StiefelPSDLayerlifts;encoder(nn)(z)appliesreverse(map(inverse_layer, ...))with the reversed parameter tree, sharing the exact same leaf arrays with zero duplicated parameters and satisfying $\Psi^e(\Psi^d(\xi)) = \xi$ to machine precision for all parametersps.
Arguments
Besides the required even integer arguments full_dim and reduced_dim (full_dim >= reduced_dim), the following keyword arguments are supported:
n_blocks::Integer = 2: Sets the spacing of the intermediate dimensions betweenreduced_dimandfull_dim(n_blocks >= 1, andn_blocks <= (full_dim - reduced_dim) ÷ 2 + 1whenfull_dim > reduced_dim; a larger value raises anArgumentErrorwhen the network is built). The decoder has one stage block per pair of adjacent dimensions, and their number can differ fromn_blocks:WeightTiedSymplecticAutoencoder(12, 2; n_blocks = 4)has five stage blocks, andWeightTiedSymplecticAutoencoder(6, 4; n_blocks = 2)has one.n_layers::Integer = 3: Number of gradient layers preceding each stagePSDLayer.n_ambient_layers::Integer = 2: Number of ambient gradient layers atfull_dimfollowing the finalPSDLayer.sympnet_upscale::Integer = 5: Upscaling factor of eachGradientLayer.activation = tanh: Activation function in the gradient layers.init_q::Bool = true: Whether the first gradient layer in each block is ofQtype.
GeometricMachineLearning.MultiModalSymplecticAutoencoder — Type
MultiModalSymplecticAutoencoder(frontends::NamedTuple, core::SymplecticCompression)Make an instance of a multi-modal symplectic autoencoder mapping a non-empty NamedTuple of modality frontends into a shared canonical latent space $\xi = (\tilde{q}, \tilde{p}) \in \mathbb{R}^{2n}$ via core.
Each entry of frontends maps a modality symbol (such as :particles, :spline, :grid, or :dlra) to a frontend layer whose output dimension equals core.full_dim = 2N. The latent state is canonical for the structure that each frontend declares; for the two parity frontends, BilinearStiefelLayer and LowRankStiefelLayer, that structure is the $\mathbb{J}_{2N}$ that they declare on the parity coordinates, not the Vlasov bracket. The frontends are:
CanonicalSortLayer,CanonicalSlotLayer,PairwiseSymplecticLayerQ,PairwiseSymplecticLayerP, or aChainof particle layers with output dimension $2N$;BilinearStiefelLayer(Nx, Nv, Mx, Mv)with $2 M_x M_v = 2N$ (with or withoutmetric_factorsfor spline vs grid modalities);LowRankStiefelLayer(Nx, Nv, Mx, Mv; r_out = ...)with $2 M_x M_v = 2N$.
Given nn = NeuralNetwork(arch, backend, T):
encode(nn, modality::Symbol, x)appliesfrontends[modality]followed byencoder(core)to map modality inputxinto $(\tilde{q}, \tilde{p}) \in \mathbb{R}^{2n}$;decode(nn, modality::Symbol, ξ)appliesdecoder(core)followed byinverse_layer(frontends[modality])to reconstruct inmodality;translate(nn, from::Symbol, to::Symbol, x)computesdecode(nn, to, encode(nn, from, x)).
GeometricMachineLearning.encode — Function
encode(nn::NeuralNetwork{<:MultiModalSymplecticAutoencoder}, modality::Symbol, x)
encode(nn::NeuralNetwork{<:MultiModalSymplecticAutoencoder}, ::Val{modality}, x)
encode(model::MultiModalSymplecticLayer, ps, modality::Symbol, x)
encode(model::MultiModalSymplecticLayer, ps, ::Val{modality}, x)
Apply frontends[modality] followed by encoder(core) to map an input x in modality modality into the shared canonical latent space $(\tilde{q}, \tilde{p}) \in \mathbb{R}^{2n}$.
Throws an ArgumentError naming modality and keys(frontends) if modality is not present in frontends.
GeometricMachineLearning.decode — Function
decode(nn::NeuralNetwork{<:MultiModalSymplecticAutoencoder}, modality::Symbol, ξ)
decode(nn::NeuralNetwork{<:MultiModalSymplecticAutoencoder}, ::Val{modality}, ξ)
decode(model::MultiModalSymplecticLayer, ps, modality::Symbol, ξ)
decode(model::MultiModalSymplecticLayer, ps, ::Val{modality}, ξ)
Apply decoder(core) followed by inverse_layer(frontends[modality]) to reconstruct a latent state $\xi$ in modality modality.
Throws an ArgumentError naming modality and keys(frontends) if modality is not present in frontends.
GeometricMachineLearning.translate — Function
translate(nn::NeuralNetwork{<:MultiModalSymplecticAutoencoder}, from::Symbol, to::Symbol, x)
translate(nn::NeuralNetwork{<:MultiModalSymplecticAutoencoder}, ::Val{from}, ::Val{to}, x)
translate(model::MultiModalSymplecticLayer, ps, from::Symbol, to::Symbol, x)
translate(model::MultiModalSymplecticLayer, ps, ::Val{from}, ::Val{to}, x)
Map an input x in modality from into modality to through the shared canonical latent space via decode(nn, to, encode(nn, from, x)).
References
- [3]
- B. Brantner and M. Kraus. Symplectic autoencoders for Model Reduction of Hamiltonian Systems, arXiv preprint arXiv:2312.10004 (2023).
- 1For the symplectic autoencoder we only use SympNet gradient layers because they seem to outperform $LA$-SympNets in many cases and are easier to interpret: their nonlinear part is the gradient of a function that only depends on half the coordinates.