SympNet Architecture
This section discusses the symplectic neural network (SympNet) architecture and its implementation in GeometricMachineLearning.
Principle
SympNets [5] are a type of neural network that can model the trajectory of a canonical Hamiltonian system in phase space. Take $(q^T,p^T)^T=(q_1,\ldots,q_d,p_1,\ldots,p_d)^T\in \mathbb{R}^{2d}$ as the coordinates in phase space, where $q=(q_1, \ldots, q_d)^T\in \mathbb{R}^{d}$ is refered to as the position and $p=(p_1, \ldots, p_d)^T\in \mathbb{R}^{d}$ the momentum. Given a point
\[ \begin{pmatrix} q^{(m)} \\ p^{(m)} \end{pmatrix} \in \mathbb{R}^{2d}\]
the SympNet aims to compute the next position
\[ \mathrm{SympNet}\left( \begin{pmatrix} q^{(m)} \\ p^{(m)} \end{pmatrix} \right) = \begin{pmatrix} \tilde{q}^{(m+1)} \\ \tilde{p}^{(m+1)} \end{pmatrix} \in \mathbb{R}^{2d}\]
and thus predicts the trajectory while preserving the symplectic structure of the system. SympNets are enforcing symplecticity strongly, meaning that this property is hard-coded into the network architecture. The layers are reminiscent of traditional neural network feedforward layers, but have a strong restriction imposed on them in order to be symplectic.
SympNets can be viewed as a symplectic integrator or symplectic one-step method[1] [1, 63]. Their goal is to predict, based on an initial condition $((q^{(0)})^T,(p^{(0)})^T)^T$, a sequence of points in phase space that fit the training data as well as possible:
\[\begin{pmatrix} q^{(0)} \\ p^{(0)} \end{pmatrix}, \begin{pmatrix} \tilde{q}^{(1)} \\ \tilde{p}^{(1)} \end{pmatrix}, \cdots \begin{pmatrix} \tilde{q}^{(n)} \\ \tilde{p}^{(n)} \end{pmatrix}.\]
The tilde in the above equation indicates predicted data. With standard SympNets[2] the time step between predictions is not a parameter we can choose but is related to the temporal frequency of the training data. This means that if data is recorded in an interval of e.g. 0.1 seconds, then this will be the time step of our integrator.
SympNets preserve symplecticity by exploiting the $(q, p)$ structure of the system. This is visualized below:
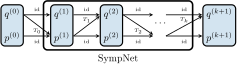
In the figure above we see that an update for $q$ is based on data coming from $p$ and an update for $p$ is based on data coming from $q$. $T_i:\mathbb{R}^d\to\mathbb{R}^d$ is an operation that changes $p$ when $i$ is even and changes $q$ when odd. It has the special property that its Jacobian is a symmetric matrix. There are two types of SympNet architectures: $LA$-SympNets and $G$-SympNets.
$LA$-SympNet
The first type of SympNets, $LA$-SympNets, are obtained from composing two types of layers: symplectic linear layers and symplectic activation layers. For a given integer $w$, the linear part of an $LA$-SympNet is
\[\mathcal{L}^{w,\mathrm{up}} \begin{pmatrix} q \\ p \\ \end{pmatrix} = \begin{pmatrix} \mathbb{I} & A^w/\mathbb{O} \\ \mathbb{O}/A^w & \mathbb{I} \\ \end{pmatrix} \cdots \begin{pmatrix} \mathbb{I} & \mathbb{O} \\ A^2 & \mathbb{I} \\ \end{pmatrix} \begin{pmatrix} \mathbb{I} & A^1 \\ \mathbb{O} & \mathbb{I} \\ \end{pmatrix} \begin{pmatrix} q \\ p \\ \end{pmatrix} + b ,\]
or
\[\mathcal{L}^{w,\mathrm{low}} \begin{pmatrix} q \\ p \end{pmatrix} = \begin{pmatrix} \mathbb{I} & \mathbb{O}/A^w \\ A^w/\mathbb{O} & \mathbb{I} \end{pmatrix} \cdots \begin{pmatrix} \mathbb{I} & A^2 \\ \mathbb{O} & \mathbb{I} \end{pmatrix} \begin{pmatrix} \mathbb{I} & \mathbb{O} \\ A^1 & \mathbb{I} \end{pmatrix} \begin{pmatrix} q \\ p \end{pmatrix} + b . \]
The superscripts $\mathrm{up}$ and $\mathrm{low}$ indicate whether the $q$ or the $p$ part is first changed[3]. The learnable parameters are the symmetric matrices $A^i\in\mathcal{S}_\mathrm{sym}(d)$ and the bias $b\in\mathbb{R}^{2d}$. The integer $w$ is the number of linear layers in one block. It can be shown that five of these layers, i.e. $w\geq{}5$, can represent any linear symplectic map [67], so $w$ need not be larger than five. We denote the set of symplectic linear layers by $\mathcal{M}^L$.
The second type of layer needed for $LA$-SympNets are activation layers.
An $LA$-SympNet is a mapping of the form $\Psi=l_{k} \circ a_{k} \circ l_{k-1} \circ \cdots \circ a_1 \circ l_0$ where $(l_i)_{0\leq i\leq k} \subset \mathcal{M}^L$ and $(a_i)_{1\leq i\leq k} \subset \mathcal{M}^A$. We will refer to $k$ as the number of hidden layers of the SympNet[4] and the number $w$ above as the depth of the linear layer.
We give an example of calling $LA$-SympNet:
using GeometricMachineLearning

k = 1
w = 2
arch = LASympNet(4;
                    nhidden = k,
                    depth = 2,
                    init_upper_linear = true,
                    init_upper_act = true,
                    activation = tanh)

model = Chain(arch).layers
(LinearLayerQ{4, 4}(), LinearLayerP{4, 4}(), GeometricMachineLearning.BiasLayer{4, 4}(), ActivationLayerQ{4, 4, typeof(tanh)}(tanh), ActivationLayerP{4, 4, typeof(tanh)}(tanh), LinearLayerQ{4, 4}(), LinearLayerP{4, 4}(), GeometricMachineLearning.BiasLayer{4, 4}())The keywords init_upper_linear and init_upper_act indicate whether the first linear (respectively activation) layer is of $q$ type[5].
$G$-SympNets
$G$-SympNets are an alternative to $LA$-SympNets. They are built with only one kind of layer, the gradient layer. If we denote by $\mathcal{M}^G$ the set of gradient layers, a $G$-SympNet is a function of the form $\Psi=g_k \circ g_{k-1} \circ \cdots \circ g_1$ where $(g_i)_{1\leq i\leq k} \subset \mathcal{M}^G$. The index $k$ here is the number of layers in the SympNet.
using GeometricMachineLearning

k = 2
n = 10
arch = GSympNet(4; upscaling_dimension = n, n_layers = k, init_upper = true, activation = tanh)

model = Chain(arch).layers
(GradientLayerQ{4, 4, typeof(tanh)}(10, tanh), GradientLayerP{4, 4, typeof(tanh)}(10, tanh))The keyword init_upper for GSympNet is similar as in the case for LASympNet. The keyword upscaling_dimension is explained in the section on the SympNet gradient layer.
Forced $G$-SympNets
A $G$-SympNet is symplectic: its map preserves the symplectic form, as the flow of a Hamiltonian system does. A damped system is not of that form: a friction or an external force enters the $\dot{p}$ equation as a term that no gradient layer can represent. A forced $G$-SympNet adds a ForcingLayer in front of every gradient layer that changes $p$:
\[\begin{pmatrix} q \\ p \end{pmatrix} \mapsto \begin{pmatrix} q \\ p + \nabla V(q) + f(z) \end{pmatrix},\]
where $f$ is a neural network of its own and $z$ the component it reads. The resulting map is in general not symplectic, which is what lets it model a non-conservative system. ForcedSympNet is the architecture, and ForcingLayer the layer it is built from.
using GeometricMachineLearning
using GeometricMachineLearning: ForcedSympNet

arch = ForcedSympNet(4; upscaling_dimension = 10, n_layers = 2, forcing_type = :P)

model = Chain(arch).layers
(GradientLayerQ{4, 4, typeof(tanh)}(10, tanh), GeometricMachineLearning.ForcingLayerP{4, 4, false, Chain{Tuple{Dense{2, 10, true, AbstractNeuralNetworks.TanhActivation}, Dense{10, 10, true, AbstractNeuralNetworks.TanhActivation}, Dense{10, 10, true, AbstractNeuralNetworks.TanhActivation}, Linear{10, 2, IdentityActivation}}}}(4, 10, 2, Chain{Tuple{Dense{2, 10, true, AbstractNeuralNetworks.TanhActivation}, Dense{10, 10, true, AbstractNeuralNetworks.TanhActivation}, Dense{10, 10, true, AbstractNeuralNetworks.TanhActivation}, Linear{10, 2, IdentityActivation}}}((Dense{2, 10, true, AbstractNeuralNetworks.TanhActivation}(AbstractNeuralNetworks.TanhActivation()), Dense{10, 10, true, AbstractNeuralNetworks.TanhActivation}(AbstractNeuralNetworks.TanhActivation()), Dense{10, 10, true, AbstractNeuralNetworks.TanhActivation}(AbstractNeuralNetworks.TanhActivation()), Linear{10, 2, IdentityActivation}(IdentityActivation())))), GradientLayerP{4, 4, typeof(tanh)}(10, tanh))The forcing_type keyword says what the forcing reads: :Q the $q$ component, :P the $p$ component, and :QP both. All three add to $p$, because that is where a forcing enters.
Universal Approximation Theorems
In order to state the universal approximation theorem for both symplectic architectures we first need a few definitions:
Let $U$ be an open set of $\mathbb{R}^{2d}$, and let us denote by $\mathcal{SP}^r(U)$ the set of $C^r$ smooth symplectic maps on $U$. We now define a topology on $C^r(K, \mathbb{R}^{2d})$, the set of $C^r$-smooth maps from a compact set $K\subset{}U$ to $\mathbb{R}^{2d}$ through the norm
\[||f||_{C^r(K,\mathbb{R}^{2d})} = \sum_{|\alpha|\leq r} \underset{1\leq i \leq 2d}{\max} \hspace{2mm} \underset{x\in K}{\sup} |D^\alpha f_i(x)|,\]
where the differential operator $D^\alpha$ is defined by
\[D^\alpha f = \frac{\partial^{|\alpha|} f}{\partial x_1^{\alpha_1}...x_n^{\alpha_n}},\]
with $|\alpha| = \alpha_1 +...+ \alpha_{2d}$. We impose the following condition ($r$ finiteness) on the activation function:
$\sigma$ is $r$-finite if $\sigma\in C^r(\mathbb{R},\mathbb{R})$ and $\int |D^r\sigma(x)|dx <\infty$.
We further consider the topology on $C^r(U, \mathbb{R}^d)$ induced by $||\cdot ||_{C^r(\cdot, \mathbb{R}^d)}$ and the associated notion of denseness:
Let $m,d,r\in \mathbb{N}$ with $m,d>0$ be given, $U$ an open subset of $\mathbb{R}^m$, and $I,J\subset C^r(U,\mathbb{R}^d)$. We say $J$ is $r$-uniformly dense on compacta in $I$ if $J \subset I$ and for any $f\in I$, $\epsilon>0$, and any compact $K\subset U$, there exists $g\in J$ such that $||f-g||_{C^r(K,\mathbb{R}^{d})} < \epsilon$.
The associated topology to this notion of denseness is the compact-open topology. It is generated by the following sets:
\[ V(K, U) := \{f\in{}C^r(\mathbb{R}^m, \mathbb{R}^d): \text{ such that $f(K)\subset{}U$}\},\]
i.e. the compact-open topology is the smallest topology that contains all sets of the form $V(K, U)$.
We can now state the universal approximation theorems:
For any positive integer $r>0$ and open set $U\in \mathbb{R}^{2d}$, the set of $LA$-SympNet is $r$-uniformly dense on compacta in $SP^r(U)$ if the activation function $\sigma$ is $r$-finite.
and
For any positive integer $r>0$ and open set $U\in \mathbb{R}^{2d}$, the set of $G$-SympNet is $r$-uniformly dense on compacta in $SP^r(U)$ if the activation function $\sigma$ is $r$-finite.
There are many $r$-finite activation functions commonly used in neural networks, for example:
- The sigmoid activation function: $\sigma(x) = {1} / (1+e^{-x})$,
- The hyperbolic tangent function: $\tanh(x) = (e^x-e^{-x}) / (e^x+e^{-x})$.
The universal approximation theorems state that we can, in principle, get arbitrarily close to any symplectomorphism defined on $\mathbb{R}^{2d}$. But this does not tell us anything about how to optimize the network. This is can be done with any common neural network optimizer and these neural network optimizers always rely on a corresponding loss function.
Loss function
To train the SympNet, one needs data along a trajectory such that the model is trained to perform an integration. The loss function is defined as[6]:
\[\mathrm{loss}(z^\mathrm{c}, z^\mathrm{p}) = \frac{|| z^\mathrm{c} - z^\mathrm{p} ||}{|| z^\mathrm{c} ||},\]
where
\[z^\mathrm{c} = \begin{pmatrix} q^\mathrm{c} \\ p^\mathrm{c} \end{pmatrix}\]
is the current state and
\[z^\mathrm{p} = \begin{pmatrix} q^\mathrm{p} \\ p^\mathrm{p} \end{pmatrix}\]
is the predicted state. In the example section we show how to use SympNets in GeometricMachineLearning.jl and how to modify the loss function.
Library Functions
GeometricMachineLearning.SympNet — Type
SympNet <: NeuralNetworkIntegratorThe SympNet type encompasses GSympNets and LASympNets. SympNets [5] are universal approximators of canonical symplectic flows. This means that for every map
\[ \varphi:\mathbb{R}^{2n}\to\mathbb{R}^{2n} \text{ with } (\nabla\varphi)^T\mathbb{J}\nabla\varphi = \mathbb{J},\]
we can find a SympNet that approximates $\varphi$ arbitrarily well.
GeometricMachineLearning.LASympNet — Type
LASympNet(d)Make an $LA$-SympNet with dimension $d.$
There exists an additional constructor that can be called by supplying an instance of DataLoader.
Examples
using GeometricMachineLearning
dl = DataLoader(rand(2, 20); suppress_info = true)
LASympNet(dl)

# output

LASympNet{typeof(tanh), true, true}(2, 5, 1, tanh)
Arguments
Keyword arguments are:
depth::Int = 5: The number of linear layers that are applied.nhidden::Int = 1: The number of hidden layers (i.e. layers that are not output layers).activation = tanh: The activation function that is applied.init_upper_linear::Bool = true: Initialize the linear layer so that it first modifies the $q$-component.init_upper_act::Bool = true: Initialize the activation layer so that it first modifies the $q$-component.
GeometricMachineLearning.GSympNet — Type
GSympNet(d)Make a $G$-SympNet with dimension $d.$
There exists an additional constructor that can be called by supplying an instance of DataLoader (see LASympNet for an example of using this constructor).
Arguments
Keyword arguments are:
upscaling_dimension::Int = 2d: The upscaling dimension of the gradient layer. See the documentation forGradientLayerQandGradientLayerPfor further explanation.n_layers::Int = 2: The number of layers (i.e. the total number ofGradientLayerQandGradientLayerP).activation = tanh: The activation function that is applied.init_upper::Bool = true: Initialize the gradient layer so that it first modifies the $q$-component.
GeometricMachineLearning.ForcedSympNet — Type
ForcedSympNet(d)Make a forced SympNet with dimension $d.$
A forced SympNet has the layer sequence of a GSympNet, with a ForcingLayer in front of every GradientLayerP, so that each step which changes $p$ also adds a learned forcing to it:
\[\begin{pmatrix} q \\ p \end{pmatrix} \mapsto \begin{pmatrix} q \\ p + \nabla V(q) + f(z) \end{pmatrix},\]
where $\nabla V$ is the gradient layer's update and $f$ the forcing layer's network, which reads $z$ — $q$, $p$ or $[q; p]$, as forcing_type says. A forced SympNet takes no parameters of the system: the forcing reads the state only. It is a NeuralNetworkIntegrator and not a SympNet: the forcing is in general not symplectic, which is what lets it model a non-conservative system.
The layer sequence follows the loop index $i \in \{1, \ldots, n\_layers\}$: for init_upper the odd $i$ is a GradientLayerQ, and the even $i$ a ForcingLayer followed by a GradientLayerP; without it, the other way around. The chain therefore holds n_layers gradient layers and one forcing layer per step that changes $p$.
d is the full phase-space dimension, which is even, so that a forcing has d ÷ 2 rows; an odd dimension raises an ArgumentError at construction.
There exists an additional constructor that can be called by supplying an instance of DataLoader.
Arguments
Keyword arguments are:
upscaling_dimension::Int = 2d: The upscaling dimension of the gradient layer. See the documentation forGradientLayerQandGradientLayerPfor further explanation. The forcing layers have this width as well.n_layers::Int = 2: The number of layers (i.e. the total number ofGradientLayerQandGradientLayerP).n_forcing_layers::Int = 2: The number of hidden layers of eachForcingLayer.activation = tanh: The activation function that is applied.init_upper::Bool = true: Initialize the gradient layer so that it first modifies the $q$-component.forcing_type::Symbol = :P: What the forcing of eachForcingLayerreads,:Q,:Por:QP.
GeometricMachineLearning.ForcingLayer — Type
ForcingLayer <: AbstractExplicitLayerA layer that adds a non-conservative term — a forcing or a dissipation — to the $p$ component of the state, and leaves the $q$ component unchanged.
A forcing enters the $\dot{p}$ equation, so every forcing layer adds to $p$. The three types of forcing layer differ in what the forcing reads: a forcing layer composes a Chain of its own with the identity on $q$,
\[\begin{pmatrix} q \\ p \end{pmatrix} \mapsto \begin{pmatrix} q \\ p + f([z; \mu]) \end{pmatrix},\]
where $f$ is the layer's network, $\mu$ the flattened parameters of the system, and $z$ is $q$ for a ForcingLayerQ, $p$ for a ForcingLayerP, and $[q; p]$ for a ForcingLayerQP. The network's last layer has dim ÷ 2 rows, so the term has the length of p whatever the type.
The step this adds a term to is the symplectic-Euler step of a GradientLayerP of a GSympNet; ForcedSympNet is the architecture that puts one in front of every such step.
Constructor
ForcingLayer(dim, width, nhidden, activation; parameters, return_parameters, type) takes the arguments and the defaults of ForcingLayerQ, and type is :Q, :P or :QP, :P by default. dim is the full phase-space dimension, as in GradientLayerQ(dim, …): the forcing has dim ÷ 2 rows. Use the constructors ForcingLayerQ, ForcingLayerP and ForcingLayerQP, which fix the type, unless you build one from a ForcedSympNet.
GeometricMachineLearning.check_forcing_type — Function
check_forcing_type(type::Symbol)Return type when it is one of the forcing types :Q, :P and :QP, and throw an ArgumentError otherwise. The type names the component that the forcing reads; every type adds to p.
GeometricMachineLearning.ForcingLayerQ — Type
ForcingLayerQ(dim, width = dim, nhidden = 1, activation = tanh; parameters, return_parameters)A forcing layer whose forcing depends only on the q component. It changes p and leaves q alone; see ForcingLayer.
Arguments
dim::Integer: the full phase-space dimension, which is even. The forcing hasdim ÷ 2rows.width::Integer = dim: the width of the layer's network.nhidden::Integer = 1: the number of hidden layers of the network.activation = tanh: the activation function of the network.
Keyword arguments
parameters = NullParameters(): the parameters of the system, which set the length of the flat vector the layer takes beside the state it reads.return_parameters::Bool = false: whether the layer returns(output, μ)instead of the output, so that the layer after it in aChainreceivesμtoo.
Examples
ForcingLayerQ(4, 8, 1, tanh; parameters = (m = 1.0,), return_parameters = false)GeometricMachineLearning.ForcingLayerP — Type
ForcingLayerP(dim, width = dim, nhidden = 1, activation = tanh; parameters, return_parameters)A forcing layer whose forcing depends only on the p component. It changes p and leaves q alone; see ForcingLayerQ for the arguments.
GeometricMachineLearning.ForcingLayerQP — Type
ForcingLayerQP(dim, width = dim, nhidden = 1, activation = tanh; parameters, return_parameters)A forcing layer whose forcing depends on the q and the p component. It changes p and leaves q alone; see ForcingLayerQ for the arguments.
References
- [5]
- P. Jin, Z. Zhang, A. Zhu, Y. Tang and G. E. Karniadakis. SympNets: Intrinsic structure-preserving symplectic networks for identifying Hamiltonian systems. Neural Networks 132, 166–179 (2020).
- 1Symplectic multi-step methods can be modeled with transformers.
- 2Recently an approach [27] has been proposed that makes explicitly specifying the time step possible by viewing SympNets as a subclass of so-called "Generalized Hamiltonian Neural Networks". Hamiltonian neural networks are implemented in HamiltonianNeuralNetworks.jl.
- 3"up" means we first change the $q$ part and "low" means we first change the $p$ part. This can be set via the keyword
init_upper_linearinLASympNet. - 4Note that if $k=0$ then the $LA$-SympNet consists of only one linear layer.
- 5Similarly to
init_upper_linear, ifinit_upper_act = truethen the first activation layer is of $q$ type, i.e. changes the $q$ component and leaves the $p$ component unchanged. - 6This loss function is implemented as
FeedForwardLossinAbstractNeuralNetworks.