Linear Symplectic Transformer
The linear symplectic transformer consists of a combination of linear symplectic attention and gradient layers and is visualized below.
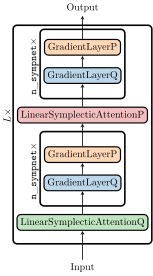
In this picture we also visualize the keywords n_sympnet and $L$ for LinearSymplecticTransformer.
What we discussed for the volume-preserving transformer also applies here: the attention mechanism acts on all the input vectors at once and is designed such that it preserves the product structure (here this is the symplectic product structure). The attention mechanism serves as a preprocessing step after which we apply a regular feedforward neural network; here this is a SympNet.
Why use Transformers for Model Order Reduction
The standard transformer, the volume-preserving transformer and the linear symplectic transformer are suitable for model order reduction for a number of reasons. Besides their improved accuracy [66] their ability to resolve time series data also makes it possible to deal with data that come from multiple parameters. For this consider the following two trajectories:
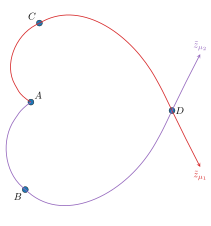
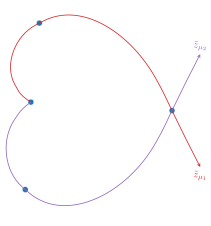
The trajectories come from a parameter-dependent ODE in two dimensions. As initial condition we take $A\in\mathbb{R}^2$ and we look at two different parameter instances: $\mu_1$ and $\mu_2$. As we can see the curves $\tilde{z}_{\mu_1}$ and $\tilde{z}_{\mu_2}$ both start out at $A,$ then go into different directions but cross again at $D.$ If we used a standard feedforward neural network to treat this system it would not be able to resolve those training data as the information would be ambiguous at points $A$ and $D,$ i.e. the network would not know what it should predict. If we however consider the information coming from points three points, either $(A, B, D)$ or $(A, C, D),$ then the network can learn to predict the next time step. We will elaborate more on this in the tutorial section.
Library Functions
GeometricMachineLearning.LinearSymplecticTransformer — Type
LinearSymplecticTransformer(sys_dim, seq_length)Make an instance of LinearSymplecticTransformer for a specific system dimension and sequence length.
Arguments
You can provide the additional optional keyword arguments:
n_sympnet::Int = (2): The number of sympnet layers in the transformer.upscaling_dimension::Int = 2*dim: The upscaling that is done by the gradient layer.L::Int = 1: The number of transformer units.activation = tanh: The activation function for the SympNet layers.init_upper::Bool=true: Specifies if the first layer is a $q$-type layer (init_upper=true) or if it is a $p$-type layer (init_upper=false).
Each transformer unit has n_sympnet gradient layers after its $q$ attention layer and n_sympnet after its $p$ attention layer, so one unit has 2n_sympnet SympNet layers. In each group of n_sympnet layers the type alternates between GradientLayerQ and GradientLayerP, starting with the type that init_upper selects. For n_sympnet = 1 and init_upper = true each group is one GradientLayerQ.